

How to Design an Integration Test That Catches Real API and Database Failures
A171-featured.webp
This guide approaches “How to Design an Integration Test That Catches Real API and Database Failures” as a practical, testable problem rather than a collection of disconnected tips. The objective is to turn the topic into measurable decisions, with particular attention to test cases, boundaries, and regression. You will get an organized analysis method, an implementation sequence, realistic failure tests, and a readiness checklist that moves the result beyond a one-time demonstration.
Define the outcome and scope
Divide the solution into layers with explicit inputs, outputs, assumptions, and success criteria, then trace the symptom back to the first layer that violates its contract. Separate functional correctness from reliability: first prove that the intended behavior is correct, then prove that it remains correct under realistic load and fault conditions. In Software Testing, test cases, boundaries, and regression often interact, so inspecting only one layer can hide the actual cause. Divide the solution into layers with explicit inputs, outputs, assumptions, and success criteria, then trace the symptom back to the first layer that violates its contract.
Prefer comparable measurements such as failure localization over screenshots or one-off demonstrations that cannot be reproduced later. Apply stable fixtures during each iteration so every observed improvement or regression can be connected to a specific change. Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster. Prefer comparable measurements such as failure localization over screenshots or one-off demonstrations that cannot be reproduced later. Apply stable fixtures during each iteration so every observed improvement or regression can be connected to a specific change.
Design the solution architecture
Divide the solution into layers with explicit inputs, outputs, assumptions, and success criteria, then trace the symptom back to the first layer that violates its contract. Separate functional correctness from reliability: first prove that the intended behavior is correct, then prove that it remains correct under realistic load and fault conditions. In Software Testing, regression, automation, and coverage often interact, so inspecting only one layer can hide the actual cause. Divide the solution into layers with explicit inputs, outputs, assumptions, and success criteria, then trace the symptom back to the first layer that violates its contract.
Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching failure localization instead of relying on appearance alone. Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed.
Prepare the implementation
Deliberately test for untested boundaries; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If coverage becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for untested boundaries; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions.
Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for slow feedback; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If defect escape rate becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct.
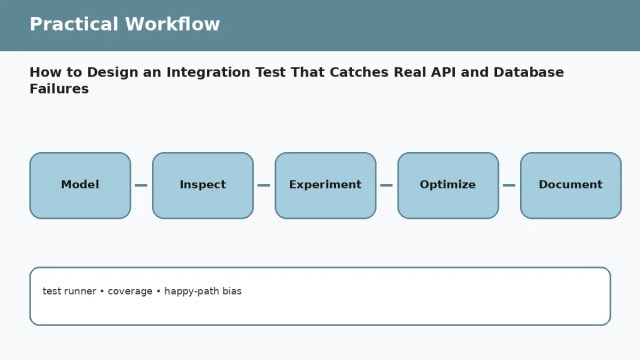
Build in a controlled sequence
One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior. Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe. Use test runner to collect direct evidence and record coverage before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior. Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe.
If runtime becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for flaky tests; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If runtime becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct.
| Area | What to check | Useful measure |
|---|---|---|
| test cases | Interaction with boundaries | coverage |
| regression | Impact of happy-path bias | defect escape rate |
| Reliability | Restart and realistic fault behavior | flakiness |
| Maintainability | Documentation and reproducibility | runtime |
First-run testing
Use coverage tools to collect direct evidence and record flakiness before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior. Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe. Use coverage tools to collect direct evidence and record flakiness before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior.
Deliberately test for overmocking; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If mean time to detect becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for overmocking; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions.
- Use test runner to verify coverage.
- Use CI to verify defect escape rate.
- Use coverage tools to verify flakiness.
- Use bug tracker to verify runtime.
- Use mocking framework to verify failure localization.
Debug and improve the system
Use mocking framework to collect direct evidence and record failure localization before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior. Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe. Use mocking framework to collect direct evidence and record failure localization before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior.
Prefer comparable measurements such as flakiness over screenshots or one-off demonstrations that cannot be reproduced later. Apply defect review during each iteration so every observed improvement or regression can be connected to a specific change. Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster. Prefer comparable measurements such as flakiness over screenshots or one-off demonstrations that cannot be reproduced later. Apply defect review during each iteration so every observed improvement or regression can be connected to a specific change.
Extend the project safely
Apply risk-based tests during each iteration so every observed improvement or regression can be connected to a specific change. Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster. Prefer comparable measurements such as runtime over screenshots or one-off demonstrations that cannot be reproduced later. Apply risk-based tests during each iteration so every observed improvement or regression can be connected to a specific change. Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster.
Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching flakiness instead of relying on appearance alone. Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching flakiness instead of relying on appearance alone.
Frequently asked questions
What should I measure first?
Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe. Use test runner to collect direct evidence and record coverage before the change so the comparison has a trustworthy baseline. One successful run does not establish reliability; repeat the scenario with different inputs and operating conditions and look for reproducible behavior. Use a small controlled reproduction before scaling up because compact test cases make state, timing, and interface mistakes easier to observe.
How do I know the solution is robust?
Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching flakiness instead of relying on appearance alone. Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random.
Which tool gives the fastest useful evidence?
If failure localization becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for weak assertions; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If failure localization becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change.
When should I redesign instead of continuing to debug?
Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching failure localization instead of relying on appearance alone. Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed.
Final readiness checklist
- Define the success criterion before changing any setting.
- Review test cases and boundaries and write down the assumptions behind them.
- Use test runner to capture a baseline measurement.
- Deliberately test for happy-path bias in a controlled way.
- Record coverage and defect escape rate before and after the change.
- Test a restart and at least one realistic fault condition.
- Document the final version and the evidence that makes the result trustworthy.
Advanced practical field notes
If coverage becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for untested boundaries; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If coverage becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change.
Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct. Deliberately test for slow feedback; a failure condition that is never exercised during testing is likely to surface later under less controlled conditions. If defect escape rate becomes worse after a modification, return to the last known-good version and compare measurements before introducing another change. Treat generated code, vendor libraries, and convenience tools as components to verify rather than as proof that the overall design is correct.
Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching defect escape rate instead of relying on appearance alone. Review boundaries between components carefully because mismatched units, timing, electrical levels, data formats, and ownership rules frequently create symptoms that appear random. Start by converting the article's main outcome into a clear success criterion that can be measured before the system is changed. Exercise resets, disconnects, invalid input, noisy conditions, and resource limits while watching defect escape rate instead of relying on appearance alone.
Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Document why the chosen solution works, not only the steps used to reach it. Record every test before drawing conclusions.
Conclusion
Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster. Prefer comparable measurements such as mean time to detect over screenshots or one-off demonstrations that cannot be reproduced later. Apply clear assertions during each iteration so every observed improvement or regression can be connected to a specific change. Record the hypothesis, the test, and the result in a short experiment log; this prevents circular troubleshooting and makes later maintenance much faster. Prefer comparable measurements such as mean time to detect over screenshots or one-off demonstrations that cannot be reproduced later. Apply clear assertions during each iteration so every observed improvement or regression can be connected to a specific change.